Model families
All five public models take RGB and projected LiDAR image tensors and produce dense semantic class logits. They differ in where the two streams meet and how features become predictions.
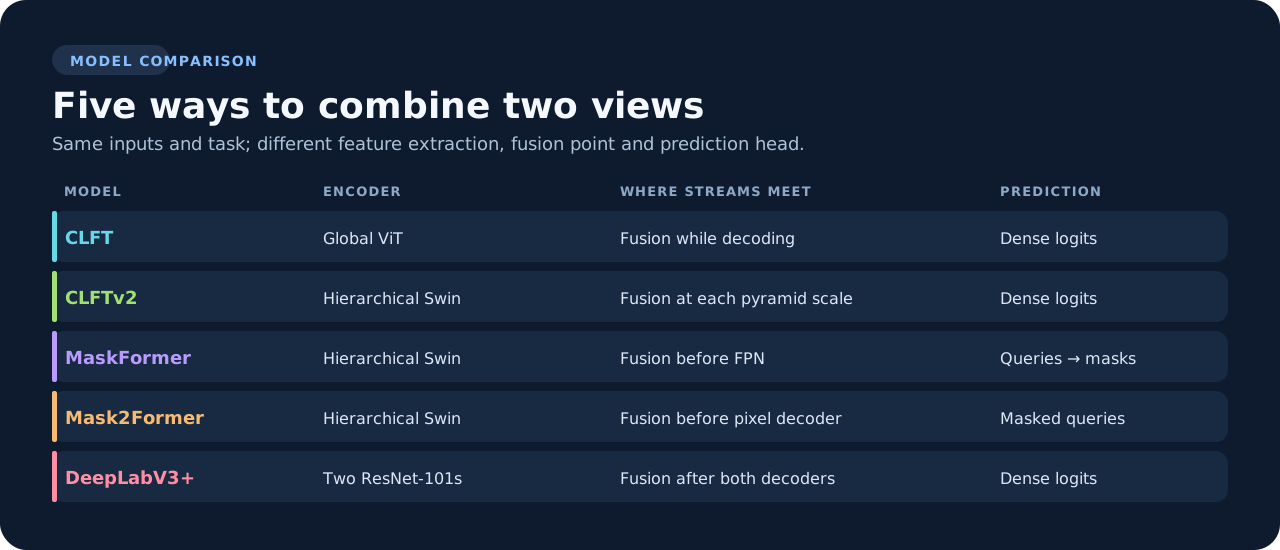
| Model | Core distinction | Read more |
|---|---|---|
| CLFT | Global ViT features are reassembled and fused during decoding. | CLFT |
| CLFTv2 | Hierarchical Swin features feed a top-down fusion pyramid. | CLFTv2 |
| MaskFormerFusion | Fused features become class-labelled masks through learned queries. | MaskFormerFusion |
| Mask2FormerFusion | A multi-scale pixel decoder feeds masked-attention queries. | Mask2FormerFusion |
| DeepLabV3+ | Two convolutional branches fuse after ASPP and decoding. | DeepLabV3+ |
The figures describe the implementations in this library. Each model page links to the relevant research paper and calls out local fusion adaptations. For constructors, inputs and training, start with the library API.